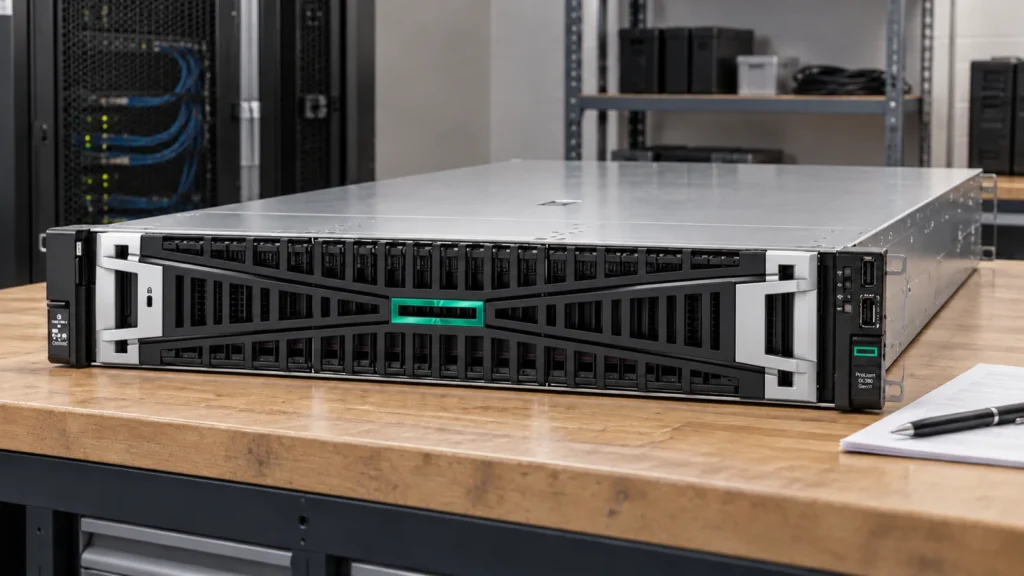
A “four-hour response time” does not mean “four hours until the application is running again”. Between a monitoring alert and a usable business process come diagnosis, approvals, rack access, a suitable spare part, technical checks and business acceptance. For a colocated server in Austria, a prepared handover between IT, the operator and the manufacturer determines whether these steps can start in parallel or have to wait for one another.
The published DAXS article on actionable Zabbix alerts covers alert quality. Here we follow the subsequent process until the application is usable again. A verified backup remains part of the recovery route if replacing a component is insufficient. The following colocation scenario and timings are explicitly fictional; they describe neither a particular DAXS customer nor a committed service level.
An alert must trigger the right work
A service cannot be reached from outside. Monitoring reports that the business transaction has failed and records the last successful check. Power and temperature readings, management access, the switch port and other hosts are examined at the same time. This helps distinguish a network issue from a failed server or application. Zabbix sends a notification only when an appropriate trigger and action are configured; recipients and escalation therefore belong in the operations plan.
Before on-site work, the ticket needs four specific details: rack and rack unit, permitted tasks, a contact with a callback route, and the serial number and location of the approved spare. Who may switch off the host? Who decides on failover? May Remote Hands replace a module, or only perform visual and cable checks? The answers must match the actual contract and data-centre access rules. Digital Realty describes Remote Hands generally as on-site technical tasks on customer equipment; this does not imply automatic availability or the same response time for every contract in Vienna.
A fictional incident in six time windows
In this example, a single virtualisation host loses its production network path. Remote diagnosis finds management access still reachable and a failed optical transceiver on the production port; a compatible, previously tested spare module is labelled and stored in the rack. This installation has no second working path. That is a deliberate weakness of the example, not a recommendation for a real design. The operator confirms the instruction before anyone works on the port.
| Time since alert | Step | Evidence / next decision |
|---|---|---|
| 0–10 minutes | Alert received and on-call contact reached | Service check and contact time recorded in the ticket |
| 10–35 minutes | Remote diagnosis of management access, port and link partner | Suspected transceiver fault; no blind hardware changes |
| 35–60 minutes | Approval, Remote Hands ticket and rack access | Specific task and callback route confirmed |
| 60–95 minutes | Identify and replace the spare module, check the link | Port status, serial number and photos documented |
| 95–125 minutes | Check host, VM and network path | Services reachable; monitoring stabilises |
| 125–140 minutes | Business department tests an order and its associated file | Only then is the business transaction approved for use again |
The 140 minutes are the sum of these invented time windows. If the fault is identified only after travel to the site, the spare is incompatible or access approval is missing, the sequence changes immediately. A hardware support contract can also define initial response, on-site arrival and repair differently. HPE explicitly distinguishes these service options and conditions; the exact product number, service zone, time and coverage must be checked before making a commitment. No external response time replaces business testing of the application.
What preparation costs over three and five years
A transparent illustrative calculation compares the same host, monitoring, service and two annual exercises. Existing server and colocation rental is excluded from both options. Common setup: 20 person-hours for the contact tree, rack documentation and runbook × an assumed fully loaded rate of €80 = €1,600. Common annual baseline: €1,200 for monitoring services, a €1,200 budget for Remote Hands without guaranteed availability, 12 × 4 maintenance hours × €80 and two exercises of eight total team-hours each × €80; together €7,520 per year.
Option A orders spare parts when an incident occurs. Option B keeps a small compatible, labelled spare kit on site: an assumed one-off €600 for components and 12 additional total team-hours to test and store them; annually an assumed €600 for storage/testing plus one extra hour each month for compatibility checks. The kit does not cover the motherboard, host or every other fault.
| Option | One-off | Annual | 3 years | 5 years |
|---|---|---|---|---|
| A · Replacement only when needed | 20 × 80 = €1,600 | 1,200 + 1,200 + 12 × 4 × 80 + 2 × 8 × 80 = €7,520 | €24,160 | €39,200 |
| B · Compatible kit on site | 1,600 + 600 + 12 × 80 = €3,160 | 7,520 + 600 + 12 × 1 × 80 = €9,080 | €30,400 | €48,560 |
Sensitivity: If the Remote Hands budget increases by €100 per month in both options, each three-year total rises by €3,600 and each five-year total by €6,000. The budget does not book guaranteed attendance time and is not a fixed data-centre price. Actual access and hourly rules, on-call windows, manufacturer service levels, component life, storage location and shipping times belong in the customer quote. The extra cost of B is worthwhile only if these particular parts address the critical fault class and genuinely save time in testing.
Clarify four points before signing the contract
First: which alerts actually trigger a staffed escalation at night, at weekends and during maintenance? Second: who may request rack access and Remote Hands from the operator and approve replacement? Third: which parts are compatible with the serial number, firmware and device, and who owns them? Fourth: how is the service approved for business use again after hardware work, failover or restore? These questions turn a product response time into a verifiable operating procedure.
DAXS can document monitoring, ticket routing, spare inventory and acceptance records for a specific colocation environment together with the customer, operator and manufacturer. Contact DAXS.
Sources: Zabbix: Problem Detection with Triggers · Digital Realty: Remote Hands Service · Digital Realty: data centres in Vienna · HPE: Tech Care service terms.