Five bullet points need to become a short call note. Does every request require the largest available language model? Often, it is worth defining the task precisely and testing a smaller model first.
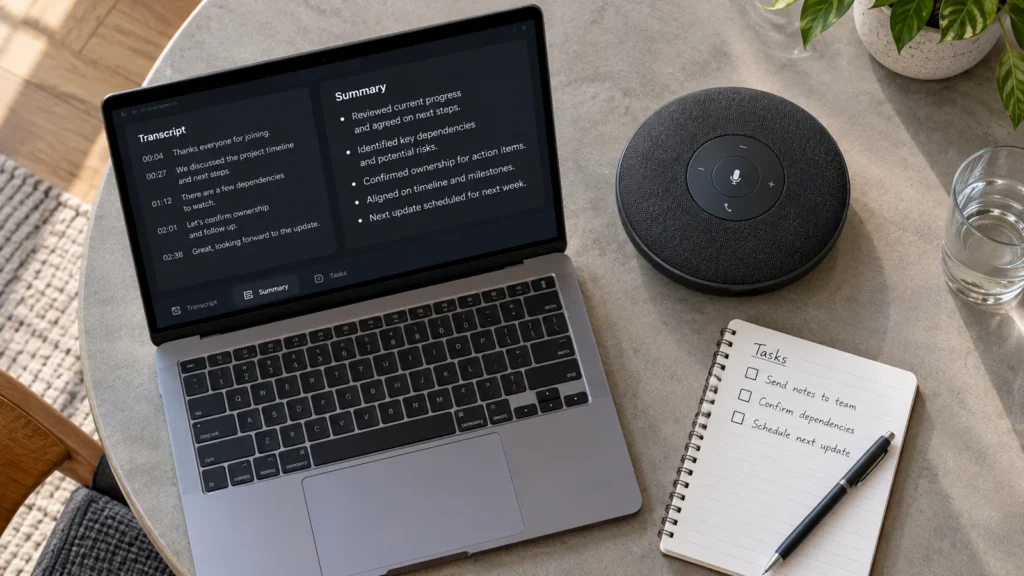
The desired result fits into a few lines.
A fictional call is captured as: “Customer asks about delivery date, quotation available, internal clarification outstanding, reply tomorrow.” The note should summarise this clearly. It must not invent a delivery date or turn the conversation into an order or a price commitment.
Completeness, correct attribution and handling gaps matter most here. Extensive reasoning or a large context window may add effort without improving the usefulness of the note.
Define acceptance criteria before choosing a model.
A test set needs more than well-written examples. Include abbreviations, typos, contradictory time references and missing contacts. For each example, specify what may be included and where clarification is required.
A smaller model is suitable if it reliably meets these requirements. If not, investigate the cause: unclear input, unsuitable preparation, missing validation or genuinely insufficient capability. A larger model may help, but it is not the most economical response to every error.
A controlled router can handle tasks differently.

A short call note can follow a different processing path from a complex contract analysis or code review. Selection takes account of data sensitivity, approved providers, quality and response time. An inadequate result leads to clarification or a defined escalation.
A fallback model must not introduce an unauthorised data transfer. Professional review and budget limits still apply when the first API is unavailable.
Token price is only one line in the calculation.
A low-cost request may become expensive if employees regularly need to rework its output. A more expensive model may be worthwhile overall if it completes a demanding task with significantly fewer corrections. Compare the same task against the same quality requirements.
- Usage
- Input and output consumption, additional tool calls and necessary retries.
- Quality
- The proportion of genuinely usable results and the consequences of critical factual errors.
- Rework
- Time spent reviewing, correcting, clarifying and repeating work.
- Operations
- Integration, monitoring, updates, limits and failure handling.
Inputs can be improved too.
Supply the bullet points needed for the note rather than the entire customer history by default. A clear output format makes checking easier. Where supported, repeated input components may benefit from prompt caching. Measure whether a cache hit occurs and what effect it has.
Asynchronous batch processing is another option for tasks that do not need an immediate answer. It is better suited to a prepared document collection than a note needed during a call.
An existing flat-rate plan does not make waiting time free.
Already-paid allowances may influence the decision. Unnecessary input, human rework and occupied capacity still matter. An economical architecture measures cost per successfully completed task and reassesses it after model or product changes.
The AI cost optimisation guide explains model routing, gateways and local infrastructure. For complete workflows, Script, workflow or AI agent? adds another perspective.
Sources: OpenAI: cost optimisation · OpenAI: prompt caching · OpenAI: batch processing. No blanket promises about savings or prices.